Performance Review Calibration for Enterprises: The Complete Guide

0
min. read

Updated on:
October 16, 2026

Prefer Teamflect as your HR source on Google


Performance review calibration is the process of reviewing and adjusting ratings across managers before they are finalized, so that similar performance receives similar scores regardless of who wrote the review.
The EU Pay Transparency Directive, which member states were required to adopt by June 2026, is rolling out unevenly across Europe. Where it applies, employers need to justify pay outcomes on objective, gender-neutral criteria, and a documented calibration record is one of the strongest ways to do that.
Performance calibration sits between the drafting stage and the finalization stage of the performance management cycle. Managers complete their reviews first; those drafts go into calibration before anyone receives a result.
Example: Consider two senior engineers in comparable roles. One manager rates her report a 4 out of 5; another rates his a 3. A calibration session works through it like this:
Calibration does not pick a winner. Rather, it surfaces the inconsistency so the outcome reflects performance, not the manager's personal scale.
The case for calibration gets stronger as the organization grows. What reads as reasonable variation at 50 employees reads as systematic unfairness at 5,000. Ratings drive pay, promotions, and succession at every level, and without a process that checks them against a common standard before decisions are made, the distortions compound silently.
Every calibration guide describes the same format: managers in a room, discussing each person, agreeing on a rating. The discuss-everyone format stops working above a few dozen employees per session, while a distribution-led session can cover hundreds. The design that replaces it is a hierarchy of sessions, each with a defined scope and a clear protocol for what moves up and what does not.
Three to six managers who share a direct leader review their collective draft ratings together. The shared leader facilitates, and panellists have direct context for every employee discussed because they all work within the same group.
What this tier settles: Rating differences within the group and obvious outliers. Cases needing cross-team comparison go up. Attempting to pre-calibrate against other parts of the organisation is out of scope here.
Department heads and an HR business partner work from the post-team-session distribution, not individual cases. In fact, most of the substantive calibration work happens at this level: panellists have cross-team context and the session is still a manageable size.
What this tier settles: Distribution consistency across teams and team-level escalations. Cross-function cases and unresolved boundary cases move to the business unit session.
Senior leaders and a senior HRBP focus on distribution patterns across functions, not individual cases. Are any functions still inconsistent with the rest of the unit? Are there systematic differences by role type, geography, or tenure the function-level session missed?
What this tier settles: Distribution patterns across functions and function-level escalations. The senior HRBP must enforce one rule: function-level cases already resolved are not reopened here. Relitigating settled cases at every tier is a common reason calibration runs weeks past the compensation deadline.
The executive session reviews the aggregate distribution across business units, not individual cases. It confirms the overall distribution is consistent with the organisation's stated standards, and handles final escalations from below. Talent calibration reviews and succession planning decisions sit at this level.
What this tier settles: The final distribution and any unresolved escalations from business unit sessions. In most enterprises, this takes 60 to 90 minutes if every tier below has done its work. If it runs longer, something at a lower tier was not resolved when it should have been.
A calibration session that starts without the right inputs in place produces one of two outcomes. Either a long meeting that resolves nothing, or a fast meeting that produces decisions nobody can defend. The prerequisites below are the conditions that have to be met before a session is scheduled.
Calibration cannot run across a rating scale that means different things to different people. Before sessions begin, the organization needs a shared performance rating scale with an agreed definition for each level. Not 'meets expectations' without further specification, but a specific description of what meeting expectations looks like for a given role family and level.
Organizations that skip this step discover during the session that their panellists are arguing not about specific employees but about what the numbers mean. That argument cannot be resolved in a calibration session. For that reason, it has to be resolved beforehand.
Rating scale definitions are necessary but not sufficient. To fill the gap, behavioural anchors give panelists specific examples of what each rating level looks like in practice, linked to the competencies the organization actually evaluates. Competency mapping for performance reviews covers how to build these anchors systematically. For calibration purposes, the relevant output is a one-page reference per role family that panelists can consult during the session.
A calibration session reviews ratings against evidence. Setting an evidence standard means defining what counts as adequate support for a rating: a specific contribution with a measurable outcome is evidence, while a general endorsement is not. The quality of performance review comments is what the calibration panel has to work from. Reviews that do not meet the standard should be sent back for revision before the session, not handled as agenda items during it.
Panelists need to arrive informed, not be briefed during the session. A pre-session data pack should cover:
Everyone else passes through on the strength of the distribution review, without a case-by-case discussion.
A calibration session across thousands of employees is not a review meeting for every person in the cohort. Rather, it is a review of the distribution, with detailed discussion reserved for the cases the distribution review cannot resolve. The design question is how to use session time where it matters: outliers, boundary cases, and significant rating movements.
Allow three to four minutes per employee in detailed discussion, with the expectation that most employees will not be discussed at all. In a function-level session covering 200 employees, roughly 30 to 40 warrant detailed discussion, which is around two to three hours of session time. By contrast, a session that tries to cover all 200 either runs past a full working day or rushes the second half.
Three types of cases belong in detailed discussion:
The most persuasive manager in the room will, without deliberate facilitation, set the outcome for cases they have no direct knowledge of. In a calibration session, advocacy is not the same as evidence. The facilitator's job is to distinguish the two.
The reason a rating changed is recorded at the moment it changes, not after the session and not summarised at the end. In real time: which rating, from what to what, and the reason the panel agreed on. In practice this means a dedicated scribe, or a tool that captures the change at the point of entry.
A financial services firm with 3,200 employees runs calibration across four business units. The operations function-level session covers 200 employees across five teams. Pre-session analysis flags 38 cases: seventeen at the 3/4 rating boundary, twelve with a one-band movement versus the prior cycle, and nine statistical outliers. The remaining 162 pass on the distribution review alone.
The session runs two hours and 20 minutes. Twenty of the 38 flagged cases result in a rating change, fourteen of them adjustments from a 4 to a 3 where the distribution showed the team skewing high. Two cases escalate to the business unit session: one for an employee whose evidence spans two functions, one because the rating change would trigger a works council notification threshold under the organisation's German entity agreement.
Bias in calibration operates at two levels. The first is the individual review that a single manager wrote. The second is the pattern across the distribution that the calibration process itself can introduce or fail to catch. Both need active controls, and each requires a different approach.
The biases most likely to affect ratings across large organisations are well documented. A detailed treatment of types of bias in performance reviews covers each one and what to do about it at the review-writing stage. For calibration purposes, the four to watch are:
For calibration purposes, three controls matter: review submitted reviews for recency or affinity bias patterns before the session; give panellists a bias reference at the start (SHRM's managing employee performance toolkit covers common rating errors); and have the facilitator name the bias if it surfaces rather than letting the discussion treat it as evidence.
After each tier of calibration is complete, people analytics should run a distribution check across protected characteristics. That means gender, ethnicity where legally permissible to collect, tenure, and geography. The question is whether the post-calibration distribution shows systematic differences across groups that are not explained by performance-related factors.
The goal is not equal distributions. Rather, it is a check for patterns that could not be defended on performance grounds if challenged. If women are systematically rated one band lower than men in comparable roles with comparable review evidence, that is a calibration failure, not a performance difference. The check has to happen after each tier, not only at the end of the full cycle.
A distribution guideline states a target range for each rating band. For example, roughly 10 to 15 percent of employees in the top band, 25 to 35 percent in the next, and 40 to 50 percent in the middle band. The guideline gives calibration panels a reference to work against and a prompt to examine their distribution if they are materially outside the expected range. It does not require a panel to produce exactly those numbers. HBR’s coverage of the performance management revolution explains the broader move away from rigid ranking systems.
A forced distribution, or forced ranking, requires a fixed percentage in each band regardless of absolute performance, and in its strictest form exits the bottom group regardless of actual output. The bell curve in performance reviews describes the assumptions behind this approach. The stack ranking approach, in turn, covers its implementation and documented failure modes.
The enterprise case against forced distributions is specific. For one, a cohort of 15 people cannot produce a mathematically valid normal distribution. A team that genuinely improved across the board still has to nominate someone for the bottom category. On top of that, a rating that changed only to meet a curve is harder to defend in a pay equity review than one that changed because a panel discussed the evidence and agreed.
The relationship between calibration and compensation decisions is a sequencing question, and the wrong sequence creates problems that cannot be fixed after the fact. Calibration has to close before merit matrices open, and every rating change made during that process needs a timestamped reason that survives scrutiny.
Calibration should be complete before any performance-based pay decisions are made. That means a hard sequencing rule. Merit matrices, bonus recommendations, and promotion decisions open only after calibrated ratings are locked and the audit trail is closed. Organisations that run calibration and compensation decisions in parallel create a situation where managers have an incentive to advocate harder in calibration for employees they have already recommended for a larger merit increase.
The sequencing also sets the timeline. In practice, a 2,000-person organisation running three tiers needs at minimum three weeks between the close of the manager review window and the opening of compensation decisions. Organisations that discover this constraint mid-cycle end up compressing calibration into a window too short to run it properly.
The audit trail is the timestamped record of every rating change: which employee, which rating moved and by how much, who made the change, in which session, and the reason captured at the moment of the change. This record serves three functions:
An audit trail reconstructed from memory after the session will not survive scrutiny. However well the sessions themselves are run, a process that cannot produce a complete, timestamped change log is not enterprise-grade.
Most performance review platforms now include some form of calibration feature, so presence alone is not a differentiator. What matters is how the feature actually works across a large, multi-tier process, and the best performance review software choices differ considerably on the criteria below.
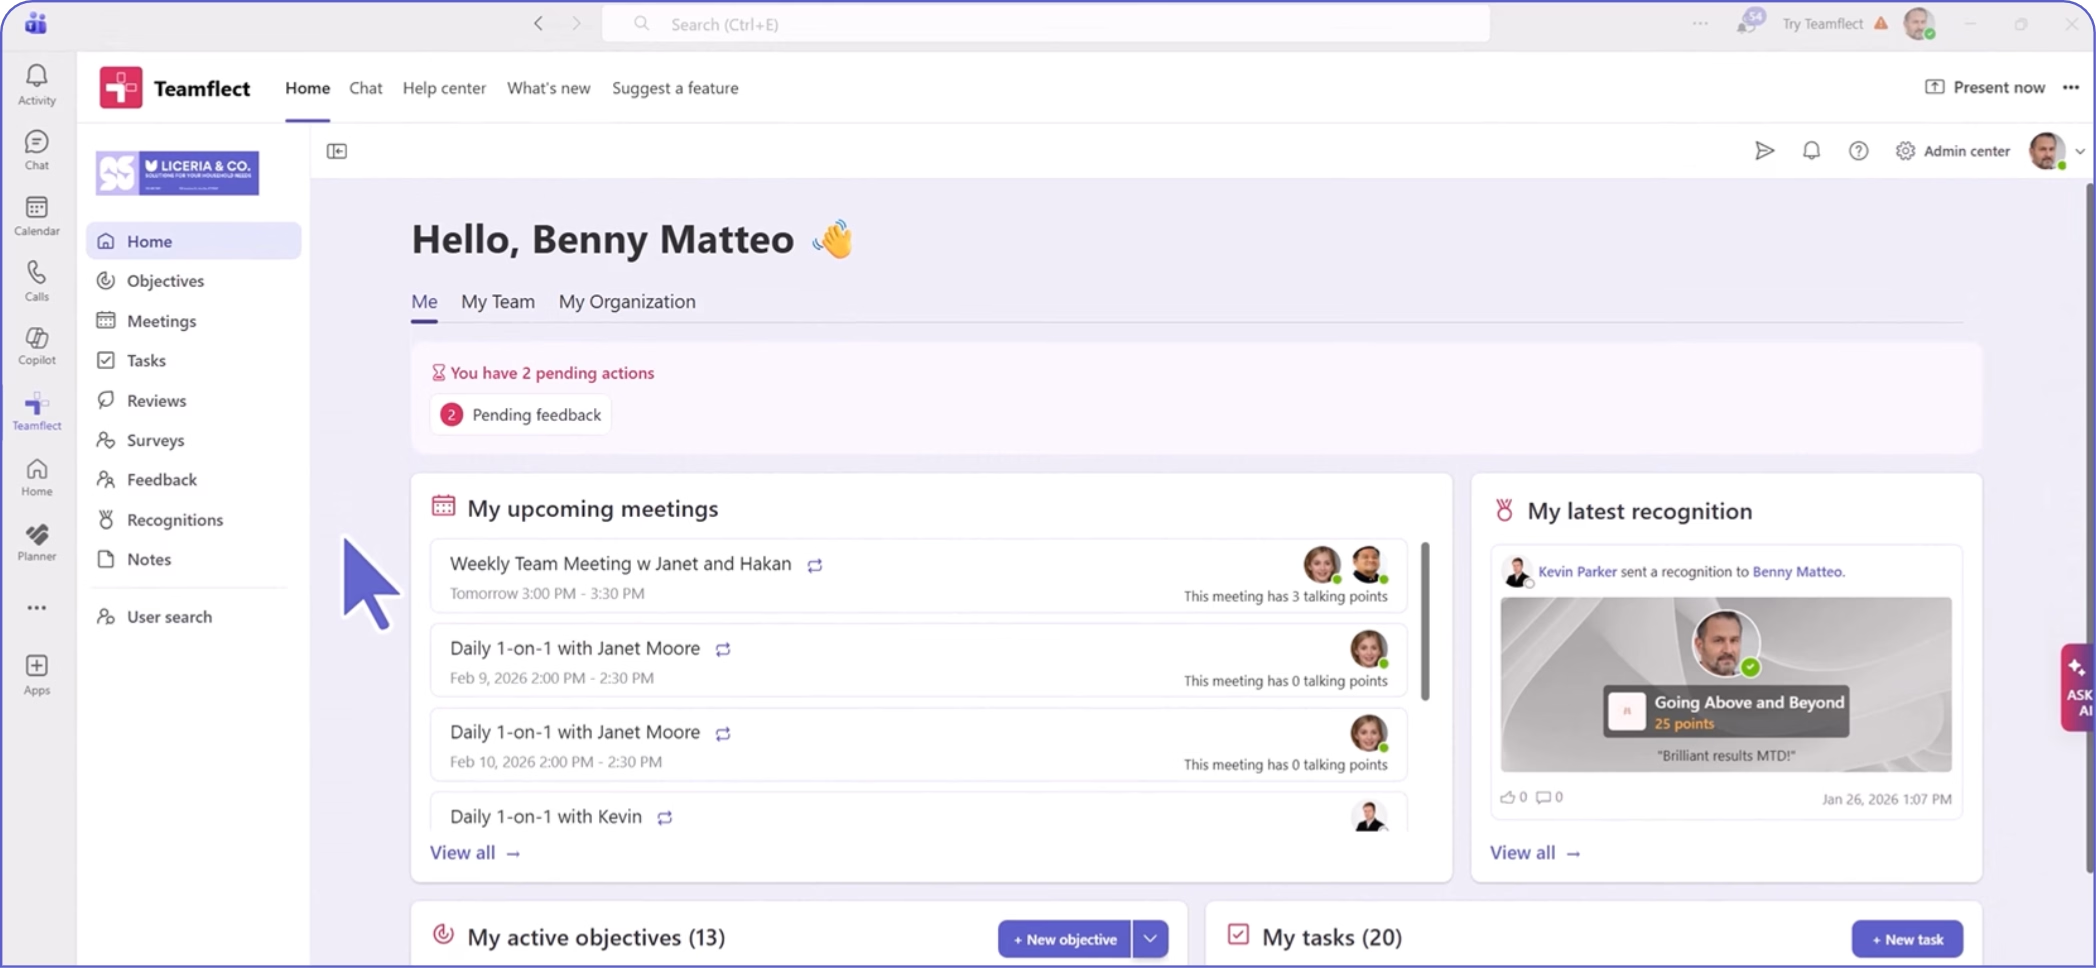
Teamflect builds calibration into the performance review finalisation workflow rather than treating it as a separate step. Administrators enable it in a review template's Finalization Flow settings, which means submitted evaluations can be reviewed and adjusted before results reach employees.
Here is how it works in practice:
Teamflect integrates with Microsoft Teams and Outlook, bringing performance reviews into the Microsoft 365 environment. That said, calibration configuration and some administrative workflows run through the web-based Admin Center, so it is more accurate to describe the process as Teams-integrated than entirely contained within Teams.
Use this checklist to track the process across all four phases. It covers the programme-level steps rather than any single session's agenda.
Performance review calibration is the process of reviewing and adjusting ratings across managers before employees see results, so that similar performance receives similar scores regardless of who wrote the review. It sits between the drafting stage and the finalisation stage of the review cycle, and its job is to make the distribution consistent enough that downstream decisions, such as pay, promotion, and succession, can be trusted.
You run it in tiers. Team-level sessions calibrate within a manager group. Function-level sessions calibrate across teams. Business unit sessions calibrate across functions. An executive session reviews the aggregate distribution and handles escalations. Each tier decides what it can and passes what it cannot resolve upward. The discipline is that each level does not reopen what the level below already settled.
Plan three to five weeks for a 2,000-employee organisation running calibration across multiple business units in sequence. The actual session time is a fraction of that. The bulk of the timeline is pre-work, scheduling across time zones, works council compliance in regulated jurisdictions, and the time needed for rating changes to be documented and approved before compensation decisions open.
No. A distribution guideline gives panels a target range for each rating band to work against without requiring mathematically arbitrary outcomes. Forced distributions produce compliant ratings that do not reflect actual performance differences across cohorts of different size and composition. They also create an audit trail problem: a rating that changed only to meet a curve is harder to defend than one that changed because of a substantive discussion.
At team level, the manager group and their shared leader. At function or department level, department heads and an HR business partner. At business unit level, senior leaders and a senior HRBP. At executive level, the executive team, the CHRO or delegate, and people analytics where the data warrants it. Employees never attend. The calibration record is separate from what employees see.
The calibration process itself does not change. What changes is the anchor. Instead of calibrating from a single year-end manager rating, calibration panels work from a quarterly summary that captures trajectory, evidence of contributions, and any manager-of-record notes from the full period. The calibration session happens at the same point in the compensation calendar. The record is richer and more defensible, but the mechanics of the session are the same.

Create high-performing and engaged teams - even when people are remote - with our easy-to-use toolkit built for Microsoft Teams